From RNA-seq to chemical enrichment: a complete workflow
Luigi Corsaro
2026-10-07
Source:vignettes/articles/tutorial_rnaseq_workflow.Rmd
tutorial_rnaseq_workflow.RmdBiological context
Dexamethasone is a synthetic glucocorticoid widely used as an anti-inflammatory and immunosuppressive agent. Its transcriptomic effects on immune cells are well characterised: it suppresses pro-inflammatory cytokines, reprograms monocyte and lymphocyte gene programmes, and leaves a distinctive signature in peripheral blood mononuclear cells (PBMCs).
This tutorial asks a straightforward question: given the RNA-seq signature of dexamethasone treatment in human PBMCs, which chemicals in the Comparative Toxicogenomics Database (CTD) share that signature?
We answer it using all four methods provided by ctdR — GSEA, ORA, CAMERA, and GSVA — and show how to visualise and interpret each result.
Data source: we use GSE311566, a public GEO series comparing the effects of PFAS chemicals and dexamethasone on human PBMCs from female donors. We work with the Dexamethasone vs. vehicle (DMSO/Ctrl) contrast, female samples only (7 samples total: 4 Ctrl + 3 Dex).
What this tutorial covers
- Downloading and preparing public RNA-seq count data from GEO
- Differential expression with
limma- Chemical enrichment analysis (GSEA, ORA, CAMERA, GSVA) using
ctdR- Visualisation with
plot_CTD()What this tutorial does NOT cover
- Raw read quality control (FastQC, trimming)
- Alignment and count generation
- Normalisation strategy selection (TMM, VST, etc.)
- Batch correction or covariate adjustment
- Biological replicate adequacy or power analysis
This is an end-to-end illustration of the
ctdRworkflow on publicly available processed data, not a template for a production differential expression pipeline.
Setup
library(ctdR)
library(limma)
library(org.Hs.eg.db)
library(AnnotationDbi)
library(SummarizedExperiment)
Step 1 — Download data from GEO
The normalised count matrix for GSE311566 is available directly from NCBI FTP. We download it once and cache it in the session temporary directory; re-running this chunk skips the download if the file already exists.
GEO_URL <- paste0(
    "https://ftp.ncbi.nlm.nih.gov/geo/series/GSE311nnn/GSE311566/",
    "suppl/GSE311566_PBMCs_Female_normalized_counts.txt.gz"
)
tmp_gz <- file.path(tempdir(), "GSE311566_Female_normalized_counts.txt.gz")
if (!file.exists(tmp_gz)) {
    message("Downloading GSE311566 from NCBI FTP ...")
    utils::download.file(GEO_URL, tmp_gz, mode = "wb", quiet = FALSE)
}
Step 2 - Build a SummarizedExperiment
counts <- utils::read.table(
    gzfile(tmp_gz),
    header = TRUE, sep = "\t", row.names = 1,
    check.names = FALSE, stringsAsFactors = FALSE
)
counts$DESCRIPTION <- NULL  # all NA in this dataset

# Female Ctrl and DEX samples only
keep_cols <- grep("^(Ctrl|DEX)_F_", colnames(counts), value = TRUE)
counts <- counts[, keep_cols]
group <- factor(
    ifelse(grepl("^DEX_", keep_cols), "Dex", "DMSO"),
    levels = c("DMSO", "Dex")
)
message(nrow(counts), " genes, ", ncol(counts), " samples: ",
    paste(table(group), names(table(group)), sep = " ", collapse = " / "))
The GEO file uses Ensembl gene IDs. We strip version suffixes and map
to Entrez IDs, which are the identifier type required by
ctdR.
ensg <- sub("\\..*$", "", rownames(counts))
entrez_map <- AnnotationDbi::mapIds(
    org.Hs.eg.db,
    keys     = ensg,
    keytype  = "ENSEMBL",
    column   = "ENTREZID",
    multiVals = "first"
)
keep_g <- !is.na(entrez_map) & !duplicated(entrez_map)
counts <- counts[keep_g, ]
rownames(counts) <- entrez_map[keep_g]
expr <- log2(as.matrix(counts) + 1)
message(nrow(expr), " genes retained after Entrez mapping")
At this point we have two objects that describe the same experiment:
a matrix of values, and a group vector saying what each
column is. Keeping them apart is where quiet errors come from. Reorder
or subset the columns of one and forget the other, and every downstream
model is fitted against the wrong labels, with nothing raising an
error.
SummarizedExperiment
is the standard Bioconductor container for exactly this situation. It
holds the assay, the per-sample annotation (colData) and
the per-gene annotation (rowData) in a single object, and
every subsetting operation moves them together.
se <- SummarizedExperiment(
    assays  = list(logcounts = expr),
    colData = DataFrame(
        sample = colnames(expr),
        group  = group,
        row.names = colnames(expr)
    ),
    metadata = list(
        source = "GEO GSE311566",
        assay_units = "log2(normalised count + 1)"
    )
)
se
#> class: SummarizedExperiment
#> dim: 37174 7
#> metadata(2): source assay_units
#> assays(1): logcounts
#> rownames(37174): 7105 64102 ... 344875 124221
#> rowData names(0):
#> colnames(7): Ctrl_F_1.counts.out Ctrl_F_2.counts.out ...
#>   DEX_F_2.counts.out DEX_F_3.counts.out
#> colData names(2): sample group
The pieces are now reachable through accessors:
assay(se) for the matrix, colData(se) for the
sample table, and se$group as a shorthand for a single
annotation column. Subsetting is safe by construction:
Step 3 — Import CTD data
ctd_csv <- "~/Downloads/CTD_chem_gene_ixns.csv"
ctd_gz  <- "~/Downloads/CTD_chem_gene_ixns.csv.gz"

if (file.exists(ctd_csv)) {
    message("Using full CTD: ", ctd_csv)
    import_CTD(ctd_csv)
} else if (file.exists(ctd_gz)) {
    message("Using full CTD (compressed): ", ctd_gz)
    import_CTD(ctd_gz)
} else {
    message(
        "Full CTD not found in ~/Downloads/ — using bundled toy sample ",
        "(10 chemicals). Results will be illustrative only.\n",
        "Download CTD_chem_gene_ixns.csv.gz from ctdbase.org for a ",
        "powered analysis."
    )
    import_CTD(system.file(
        "extdata", "CTD_chem_gene_ixns_sample.csv",
        package = "ctdR"
    ))
}
Note on CTD coverage: this tutorial uses the small toy dataset bundled with
ctdR(10 chemicals, 17 genes). It is sufficient to demonstrate the API and visualisations. For a powered analysis capable of discovering novel chemical associations, download the fullCTD_chem_gene_ixns.csv.gzfrom https://ctdbase.org/reports/CTD_chem_gene_ixns.csv.gz and runimport_CTD()on that file instead.
Step 4 — Differential expression with limma
We fit a linear model and apply empirical Bayes moderation. The
design matrix has two columns: the intercept (DMSO baseline) and
groupDex (Dex vs DMSO contrast, coefficient 2).
design <- model.matrix(~ se$group)
colnames(design) <- c("(Intercept)", "groupDex")
colnames(design)
#> [1] "(Intercept)" "groupDex"

fit <- limma::lmFit(assay(se), design)
fit <- limma::eBayes(fit)

de <- limma::topTable(fit, coef = 2, n = Inf, sort.by = "P")
de$EntrezID <- rownames(de)

head(de[, c("EntrezID", "logFC", "t", "P.Value", "adj.P.Val")])
#>       EntrezID      logFC         t      P.Value   adj.P.Val
#> 2289      2289  2.8860368  66.81282 5.381612e-09 0.000200056
#> 64744    64744  1.5371202  33.39116 2.148090e-07 0.002665942
#> 8553      8553 -1.2969205 -33.38130 2.151457e-07 0.002665942
#> 8761      8761  0.7060472  27.55983 5.941309e-07 0.005521555
#> 8395      8395 -0.9214413 -25.57857 8.817929e-07 0.006555954
#> 78999    78999  0.9863471  23.27464 1.452352e-06 0.008998287
A brief look at significance:
Step 5 — Chemical enrichment
GSEA — Gene Set Enrichment Analysis
GSEA uses the full ranked gene list to detect
chemicals whose known target genes collectively cluster toward one
extreme of the ranking, without requiring a significance threshold. We
supply the moderated t-statistic from limma as the stat
column so that directionality (up vs down) is preserved and ties at
non-significant genes are avoided. Pass nproc = N to
parallelise across N cores.
gsea_input <- data.frame(
    EntrezID = de$EntrezID,
    pvalue   = de$P.Value,
    stat     = de$t,       # signed ranking: positive = up in Dex
    row.names = NULL
)
gsea_results <- enrichment_CTD(
    gsea_input, method = "GSEA",
    minSize = 3, maxSize = 500   # gene set size filter
)
head(gsea_results[, c(
    "ChemicalName", "PValue", "PValueAdjusted",
    "NormalizedEnrichmentScore", "GeneSetSize"
)])
#>       ChemicalName     PValue PValueAdjusted NormalizedEnrichmentScore
#> 1        Estradiol 0.02328381      0.2328381                -1.4470219
#> 2    Acetaminophen 0.74846626      0.9355828                 0.7939608
#> 3   Benzo(a)pyrene 0.71342685      0.9355828                 0.8077455
#> 4          Cadmium 0.73456790      0.9355828                 0.7949407
#> 5        Cisplatin 0.73630832      0.9355828                 0.7844192
#> 6 Cyclophosphamide 0.73809524      0.9355828                -0.8136112
#>   GeneSetSize
#> 1           6
#> 2          12
#> 3          10
#> 4           8
#> 5          11
#> 6 5NES, the normalized enrichment score, is the statistic
to compare between chemicals: it scales the raw enrichment score for
gene set size, which is what makes two sets of different sizes
comparable at all. Its sign carries the direction, positive for targets
clustering at the top of the ranking and negative for the bottom.
Earlier versions also reported a FoldEnrichment for
GSEA, computed as |ES| / mean(ES) across the chemicals
tested in the same run. That made it a property of the run rather than
of the chemical, so it has been removed. Fold enrichment in this package
now means one thing, the observed-over-expected ratio ORA reports.
plot_CTD(gsea_results, type = "bar", n = 10,
         title = "GSEA — top chemicals by NES")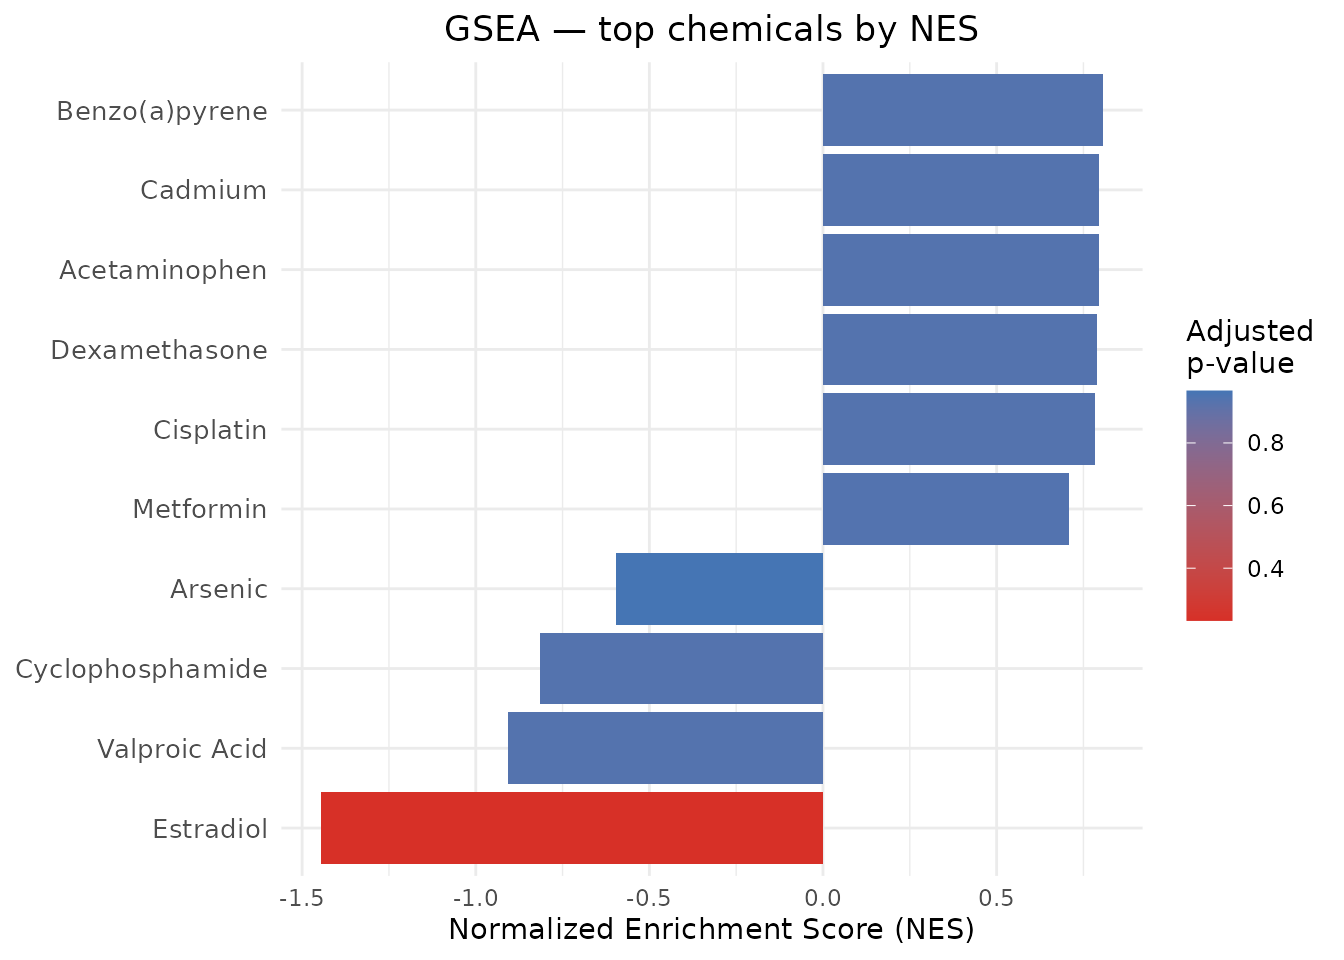
plot_CTD(gsea_results, type = "dot", n = 10,
         title = "GSEA — top chemicals (dot)")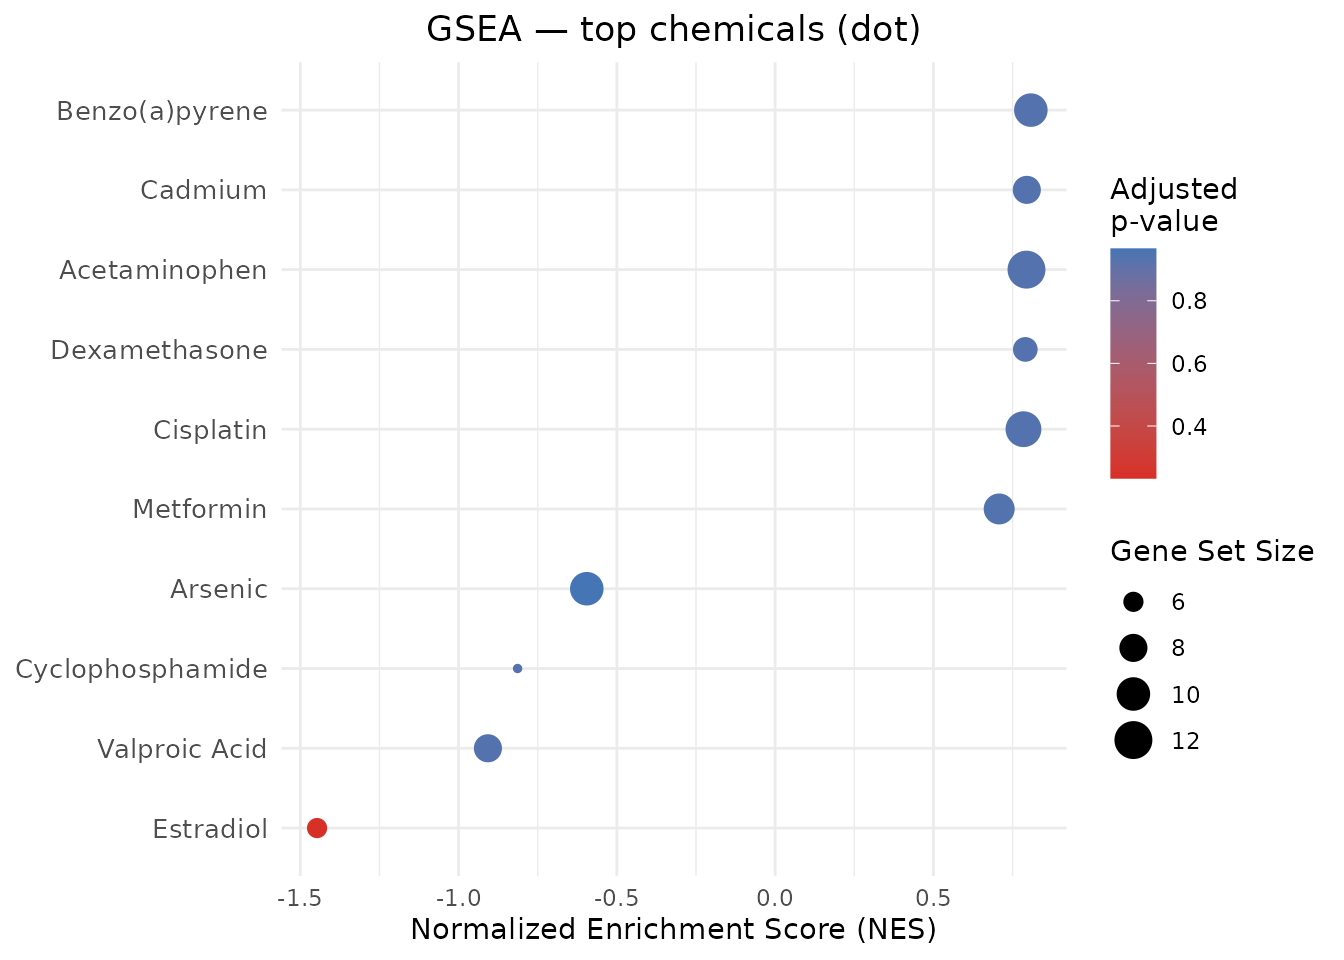
Where is Dexamethasone?
The top-ranked chemical may or may not be Dexamethasone depending on which CTD dataset is loaded. With the full CTD (~11 000 chemicals and strict BH correction) Dexamethasone competes against many other chemicals and may rank lower than expected, or may not reach significance after correction. The code below locates it regardless of its rank:
dex_idx  <- grep("dexamethasone", gsea_results$ChemicalName,
                 ignore.case = TRUE)
if (length(dex_idx) > 0) {
    cat("Dexamethasone: rank", dex_idx, "of", nrow(gsea_results), "\n")
    gsea_results[dex_idx, c("ChemicalName", "PValue", "PValueAdjusted",
                             "NormalizedEnrichmentScore", "GeneSetSize")]
} else {
    message("Dexamethasone not found — it may be absent from the loaded CTD cache.")
}
#> Dexamethasone: rank 7 of 10
#>    ChemicalName    PValue PValueAdjusted NormalizedEnrichmentScore GeneSetSize
#> 7 Dexamethasone 0.7396694      0.9355828                 0.7902494           7
Why Dexamethasone may not top the list with the full CTD:
- Multiple testing burden — 11 000 tests vs 10 in the toy sample; the BH threshold is ~1 000× more stringent.
- Larger gene sets — in the full CTD, Dexamethasone has hundreds of annotated targets; very large sets dilute the GSEA signal in small cohorts (7 samples here).
- Competing chemicals — other chemicals may have gene sets that overlap more tightly with the top-ranked DE genes.
Direction-aware GSEA with interaction_types
The standard GSEA above uses all CTD interactions regardless of
direction. With interaction_types we can restrict each
chemical’s gene set to interactions of a specific type, creating a
concordance test: do chemicals that are known to
increase gene expression share targets with genes we observe
up-regulated?
# Chemicals whose INCREASE-expression targets are enriched among up-regulated genes
gsea_up <- enrichment_CTD(
    gsea_input, method = "GSEA",
    minSize = 3, maxSize = 500,
    interaction_types = "increases^expression"
)

# Chemicals whose DECREASE-expression targets are enriched among down-regulated genes
# Flip stat sign so down-regulated genes (negative t) rank at the top
gsea_input_down <- transform(gsea_input, stat = -stat)
gsea_down <- enrichment_CTD(
    gsea_input_down, method = "GSEA",
    minSize = 3, maxSize = 500,
    interaction_types = "decreases^expression"
)

# Chemicals consistent with Dex treatment (up or down, direction-matched)
message("Direction-aware GSEA — increases^expression: ",
        nrow(gsea_up), " chemicals tested")
message("Direction-aware GSEA — decreases^expression: ",
        nrow(gsea_down), " chemicals tested")
A chemical appearing in both gsea_up
and gsea_down with positive NES in each is particularly
strong evidence of a concordant transcriptomic footprint.
ORA — Over-Representation Analysis
ORA works on a binary gene list: genes declared significant vs the rest of the universe. It asks whether the overlap between your significant genes and each chemical’s known targets is larger than expected by chance (hypergeometric test).
sig <- de[de$adj.P.Val < 0.05, c("EntrezID", "P.Value")]
colnames(sig)[2] <- "pvalue"
message(nrow(sig), " genes at adj.P.Val < 0.05")

# Both size thresholds are left at their defaults, which are chosen for
# CTD rather than inherited: minGSSize = 2 because the median chemical
# has 4 target genes, and no upper limit because no CTD gene set is
# large enough to be untestable. A cap at 500 would exclude
# dexamethasone, which is the treatment this experiment applied. See the
# package vignette for the measurements.
ora_results <- enrichment_CTD(
    sig, method = "ORA",
    universe   = de$EntrezID  # restrict background to measured genes
)
if (nrow(ora_results) > 0) {
    head(ora_results[, c(
        "ChemicalName", "PValue", "PValueAdjusted",
        "FoldEnrichment", "Count", "EnrichedGenes"
    )])
} else {
    message(
        "ORA returned 0 results — expected with the toy CTD sample.\n",
        "Run import_CTD() on the full CTD file for a powered analysis."
    )
}
if (nrow(ora_results) > 0) {
    dex_idx <- grep("dexamethasone", ora_results$ChemicalName,
                    ignore.case = TRUE)
    if (length(dex_idx) > 0) {
        cat("Dexamethasone: rank", dex_idx, "of", nrow(ora_results), "\n")
        ora_results[dex_idx, c("ChemicalName", "PValue", "PValueAdjusted",
                                "FoldEnrichment", "Count")]
    } else {
        message("Dexamethasone not found in ORA results.")
    }
}
plot_CTD(ora_results, type = "dot", n = 10,
         title = "ORA — top chemicals by fold enrichment")
FoldEnrichment in ORA is
GeneRatio / BackgroundRatio: the proportion of your
significant genes that are targets of this chemical, divided by the same
proportion in the background universe. A value greater than 1 indicates
over-representation.
CAMERA — Competitive gene-set test
CAMERA tests, for each chemical, whether its target genes show a stronger differential signal than the rest of the transcriptome, while correcting for inter-gene correlation within the gene set. It is particularly well suited to expression matrix experiments with a clear design and contrast.
CAMERA does not consume a pre-computed DEG result: it takes the
full expression data plus a
design and a
contrast, and recomputes the differential
signal internally. It accepts the SummarizedExperiment
directly, so we hand it se rather than pulling the assay
back out. The chemical to gene “index” is built by ctdR
from CTD targets. We reuse the design matrix built for
limma; here design carries the whole layout while
contrast = 2 selects which coefficient to test,
the groupDex effect (Dex vs DMSO).
camera_results <- enrichment_CTD(
    se,
    method   = "CAMERA",
    design   = design,
    contrast = 2
)
head(camera_results[, c(
    "ChemicalName", "PValue", "PValueAdjusted",
    "GeneSetSize", "Direction"
)])
#>     ChemicalName     PValue PValueAdjusted GeneSetSize Direction
#> 1      Estradiol 0.02495925      0.2495925           6      Down
#> 2  Acetaminophen 0.26645058      0.5007785          12        Up
#> 3 Benzo(a)pyrene 0.31813538      0.5007785          10        Up
#> 4        Cadmium 0.16732813      0.5007785           8        Up
#> 5      Cisplatin 0.31687483      0.5007785          11        Up
#> 6  Dexamethasone 0.33074736      0.5007785           7        Up
CAMERA reports Direction ("Up" or
"Down"), indicating whether the chemical’s target genes are
predominantly up- or down-regulated under the tested contrast. Each
method reports the effect size its test actually produces: fold
enrichment for ORA, NES for GSEA, direction for CAMERA.
plot_CTD(camera_results, type = "bar", n = 10,
         title = "CAMERA — direction-aware chemical enrichment")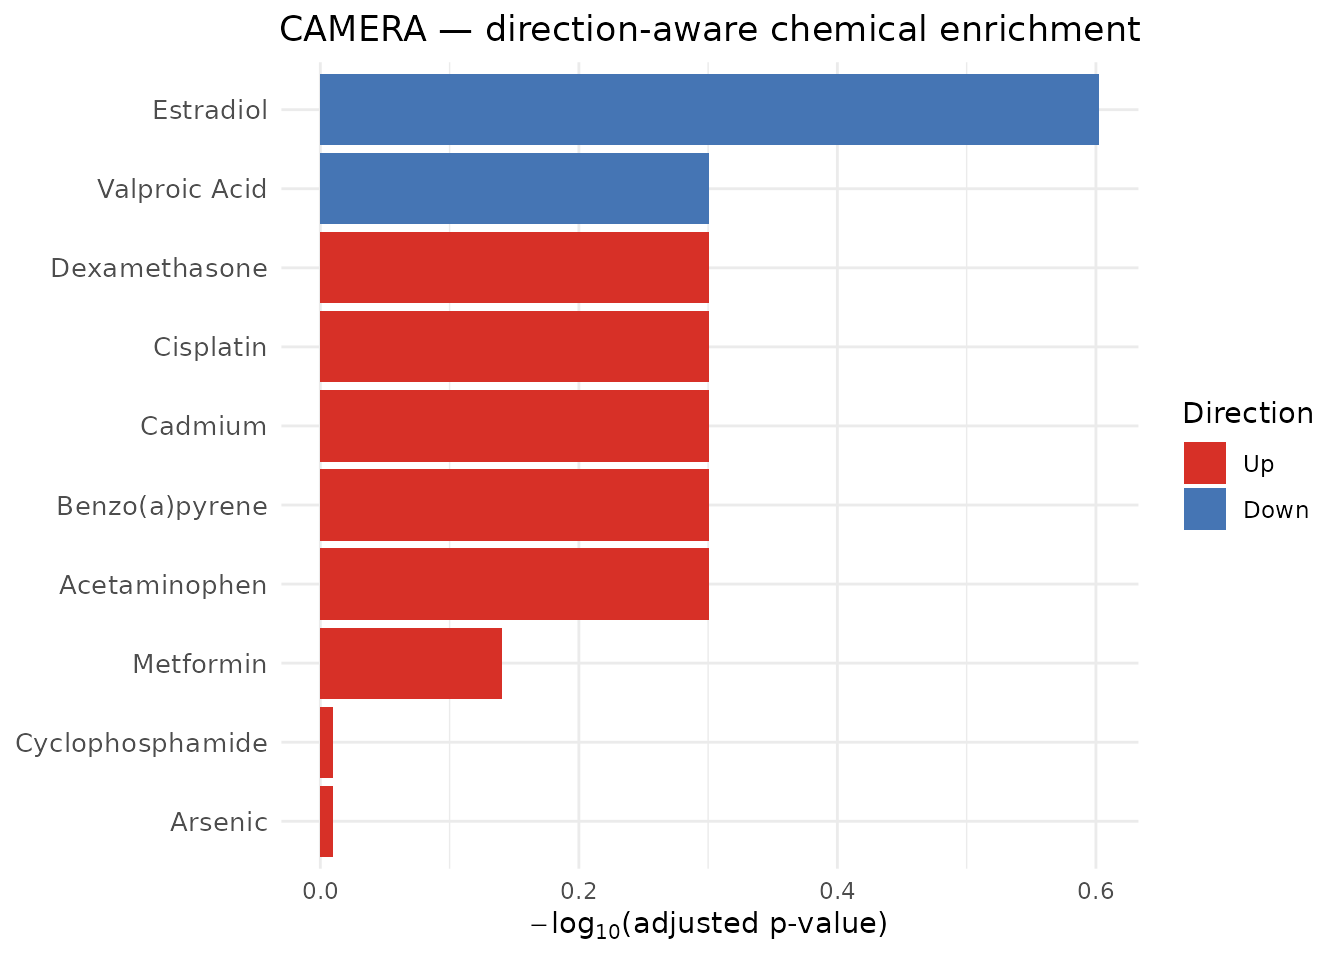
dex_idx <- grep("dexamethasone", camera_results$ChemicalName,
                ignore.case = TRUE)
if (length(dex_idx) > 0) {
    cat("Dexamethasone: rank", dex_idx, "of", nrow(camera_results), "\n")
    camera_results[dex_idx, c("ChemicalName", "PValue", "PValueAdjusted",
                               "GeneSetSize", "Direction")]
} else {
    message("Dexamethasone not found in CAMERA results.")
}
#> Dexamethasone: rank 6 of 10
#>    ChemicalName    PValue PValueAdjusted GeneSetSize Direction
#> 6 Dexamethasone 0.3307474      0.5007785           7        Up
GSVA — Gene Set Variation Analysis
GSVA produces a per-sample enrichment score for each chemical, with chemicals in rows and samples in columns. There is no single group-level p-value; instead, these scores can be used for clustering, heatmap visualisation, survival association, or as input to downstream tests.
Because those scores are per sample, the sample annotation is what
makes them interpretable. GSVA returns the container it was given: hand
it the SummarizedExperiment and the scores come back as one
too, with colData carried across, so the treatment groups
stay attached to the numbers they describe.
Computation time: GSVA scores all chemicals across all samples. On the full expression matrix this may take a few minutes. Use
BiocParallel::register()to speed it up on multi-core machines.
gsva_scores <- enrichment_CTD(
    se, method = "GSVA",
    minSize = 3, maxSize = 500
)
dim(gsva_scores)  # chemicals x samples
#> [1] 10  7

# the design annotation survived the analysis
colData(gsva_scores)
#> DataFrame with 7 rows and 2 columns
#>                                  sample    group
#>                             <character> <factor>
#> Ctrl_F_1.counts.out Ctrl_F_1.counts.out     DMSO
#> Ctrl_F_2.counts.out Ctrl_F_2.counts.out     DMSO
#> Ctrl_F_3.counts.out Ctrl_F_3.counts.out     DMSO
#> Ctrl_F_4.counts.out Ctrl_F_4.counts.out     DMSO
#> DEX_F_1.counts.out   DEX_F_1.counts.out     Dex
#> DEX_F_2.counts.out   DEX_F_2.counts.out     Dex
#> DEX_F_3.counts.out   DEX_F_3.counts.out     Dex
plot_CTD(gsva_scores,
         title = "GSVA: per-sample chemical enrichment scores")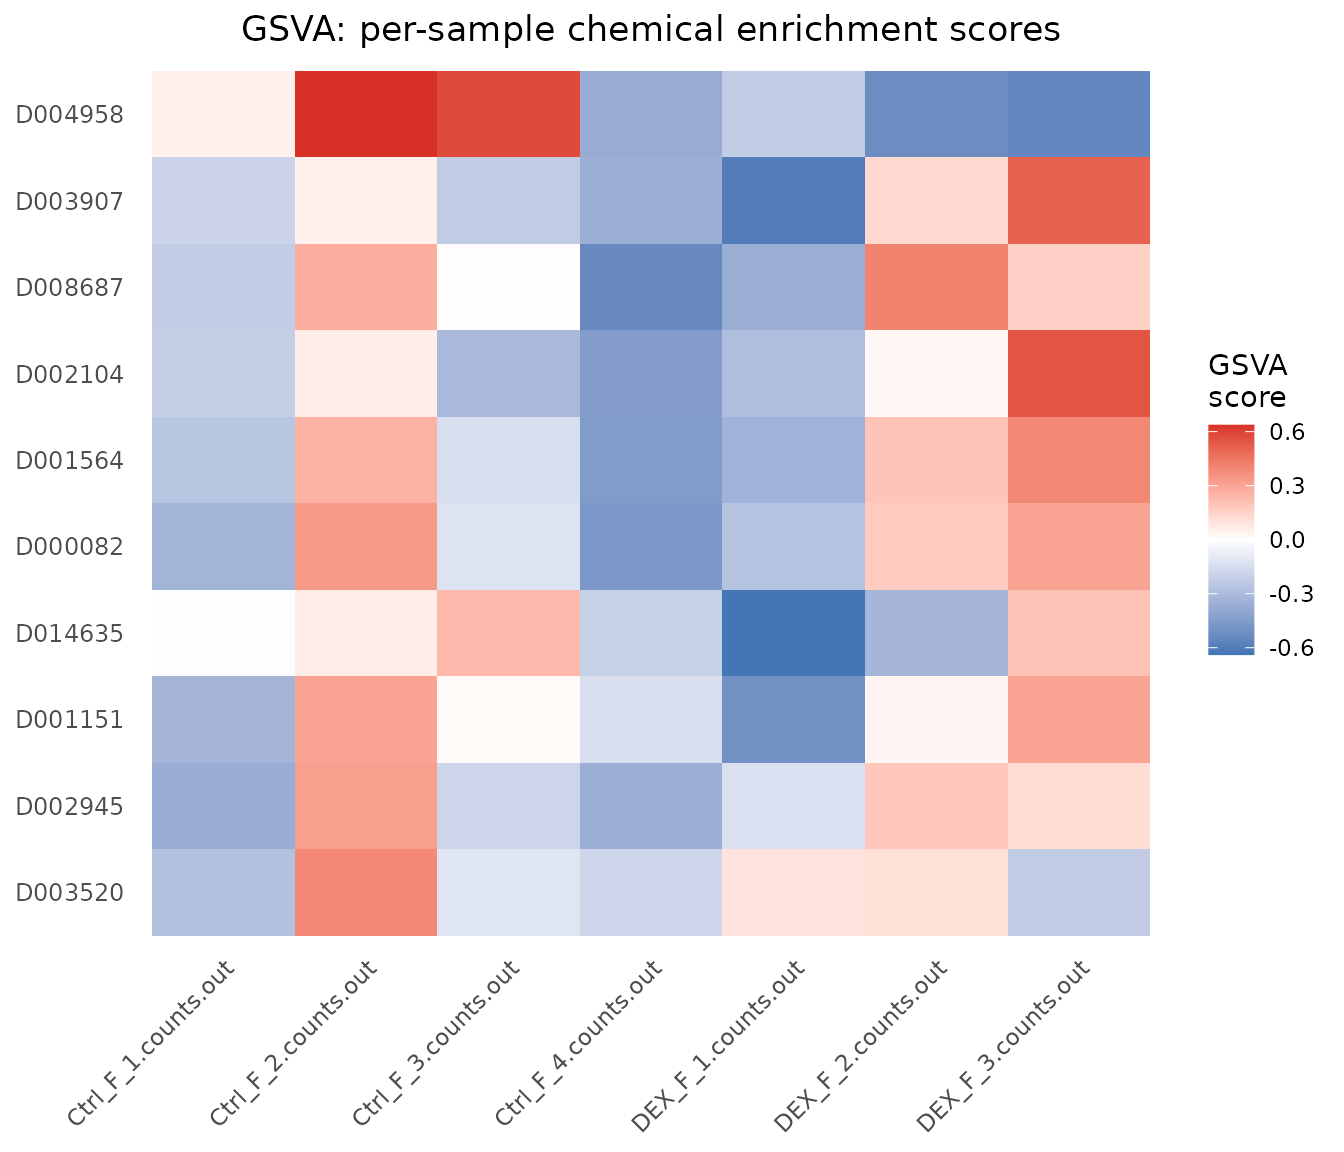
The heatmap rows are chemicals ranked by across-sample variance (top-variance chemicals shown first). Samples that cluster together share a similar chemical-exposure transcriptomic profile.
To inspect Dexamethasone’s per-sample scores directly:
dex_idx <- grep("dexamethasone", rownames(gsva_scores),
                ignore.case = TRUE)
if (length(dex_idx) > 0) {
    cat("Dexamethasone row(s):", rownames(gsva_scores)[dex_idx], "\n")
    # scores side by side with the group each sample belongs to
    data.frame(
        group = gsva_scores$group,
        score = as.vector(assay(gsva_scores)[dex_idx[1], ]),
        row.names = colnames(gsva_scores)
    )
} else {
    message("Dexamethasone not found in GSVA scores.")
}
Positive scores indicate that Dexamethasone’s target genes are collectively up-regulated in that sample relative to the background; negative scores indicate down-regulation. A clear separation between Dex and Ctrl samples (positive scores in Dex, negative in Ctrl, or vice versa) would support the expected glucocorticoid signature.
Step 6 — Comparing results across methods
Each method answers a subtly different question:
| Method | Input | Question answered | Key output column |
|---|---|---|---|
| GSEA | Full ranked list | Do this chemical’s targets cluster at the extreme of the ranking? | NES |
| ORA | Significant gene list | Is the overlap larger than expected by chance? |
FoldEnrichment, Count
|
| CAMERA | Expression matrix + design | Is the differential signal stronger than the transcriptome average? | Direction |
| GSVA | Expression matrix | What is the per-sample enrichment score? | score matrix |
Each method’s effect size answers its own question, so there is
nothing to compare across the last column. FoldEnrichment
is ORA’s and means the ratio of observed to expected overlap;
NES is GSEA’s and means the enrichment score scaled for
gene set size. Earlier versions gave both methods a column called
FoldEnrichment, which invited exactly the comparison that
does not hold.
For a discovery workflow on a single contrast, GSEA is recommended as the primary method — it uses all genes and is robust to the choice of significance threshold. ORA is useful as a complementary check when a reliable binary gene list is available. CAMERA is the method of choice when inter-gene correlation is a concern. GSVA is best reserved for multi-sample stratification or when you want to visualise chemical signatures across a cohort.
Dexamethasone — ranking recap across all methods
Since Dexamethasone is the treatment used in GSE311566, we expect its CTD gene set to carry a strong signal in this dataset. The code below collects its position and key statistics from each method into a single summary, regardless of whether it reached the top rank.
dex_gsea <- local({
    idx <- which(tolower(gsea_results$ChemicalName) == "dexamethasone")
    if (length(idx) == 0L) return(NULL)
    r <- gsea_results[idx, ]
    data.frame(
        Method    = "GSEA",
        Rank      = idx,
        Total     = nrow(gsea_results),
        PValue    = signif(r$PValue, 3),
        PAdj      = signif(r$PValueAdjusted, 3),
        StatLabel = "NES",
        Stat      = signif(r$NormalizedEnrichmentScore, 3)
    )
})
dex_ora <- local({
    if (nrow(ora_results) == 0L) return(NULL)
    idx <- which(tolower(ora_results$ChemicalName) == "dexamethasone")
    if (length(idx) == 0L) return(NULL)
    r <- ora_results[idx, ]
    data.frame(
        Method    = "ORA",
        Rank      = idx,
        Total     = nrow(ora_results),
        PValue    = signif(r$PValue, 3),
        PAdj      = signif(r$PValueAdjusted, 3),
        StatLabel = "FoldEnrichment",
        Stat      = signif(r$FoldEnrichment, 3)
    )
})
dex_camera <- local({
    idx <- which(tolower(camera_results$ChemicalName) == "dexamethasone")
    if (length(idx) == 0L) return(NULL)
    r <- camera_results[idx, ]
    data.frame(
        Method    = "CAMERA",
        Rank      = idx,
        Total     = nrow(camera_results),
        PValue    = signif(r$PValue, 3),
        PAdj      = signif(r$PValueAdjusted, 3),
        StatLabel = "Direction",
        Stat      = r$Direction
    )
})
dex_gsva <- local({
    # GSVA rownames are ChemicalIDs (e.g. "D003907"), not names.
    # Retrieve the chemicals metadata from the cache to map name -> ID.
    chem <- ctd_cache("chemicals")
    dex_id <- chem$ChemicalID[
        tolower(chem$ChemicalName) == "dexamethasone"
    ]
    if (length(dex_id) == 0L || !dex_id %in% rownames(gsva_scores))
        return(NULL)
    scores <- assay(gsva_scores)[dex_id, , drop = FALSE]
    # group membership comes from colData, not from parsing sample names
    dex_samples  <- gsva_scores$group == "Dex"
    ctrl_samples <- gsva_scores$group == "DMSO"
    mean_dex     <- mean(scores[, dex_samples])
    mean_ctrl    <- mean(scores[, ctrl_samples])
    data.frame(
        Method    = "GSVA",
        Rank      = NA_integer_,
        Total     = nrow(gsva_scores),
        PValue    = NA_real_,
        PAdj      = NA_real_,
        StatLabel = "mean(Dex) - mean(Ctrl)",
        Stat      = signif(mean_dex - mean_ctrl, 3)
    )
})
recap <- do.call(rbind, Filter(Negate(is.null),
                               list(dex_gsea, dex_ora, dex_camera, dex_gsva)))

if (is.null(recap) || nrow(recap) == 0L) {
    message("Dexamethasone not found in any method's results.")
} else {
    recap$RankOf <- ifelse(
        is.na(recap$Rank), "—",
        paste0(recap$Rank, " / ", recap$Total)
    )
    print(recap[, c("Method", "RankOf", "PValue", "PAdj",
                    "StatLabel", "Stat")],
          row.names = FALSE)
}
#>  Method RankOf PValue  PAdj              StatLabel  Stat
#>    GSEA 7 / 10  0.740 0.936                    NES  0.79
#>  CAMERA 6 / 10  0.331 0.501              Direction    Up
#>    GSVA      —     NA    NA mean(Dex) - mean(Ctrl) 0.195
RankOf is the position of Dexamethasone in each result
table sorted by adjusted p-value (GSEA, ORA, CAMERA) or — for GSVA — the
difference between the mean per-sample score in treated vs control
samples (positive = target genes up-regulated in Dex samples).
Session information
sessionInfo()
#> R version 4.6.1 (2026-06-24)
#> Platform: x86_64-pc-linux-gnu
#> Running under: Ubuntu 24.04.5 LTS
#>
#> Matrix products: default
#> BLAS:   /usr/lib/x86_64-linux-gnu/openblas-pthread/libblas.so.3
#> LAPACK: /usr/lib/x86_64-linux-gnu/openblas-pthread/libopenblasp-r0.3.26.so;  LAPACK version 3.12.0
#>
#> locale:
#>  [1] LC_CTYPE=C.UTF-8       LC_NUMERIC=C           LC_TIME=C.UTF-8
#>  [4] LC_COLLATE=C.UTF-8     LC_MONETARY=C.UTF-8    LC_MESSAGES=C.UTF-8
#>  [7] LC_PAPER=C.UTF-8       LC_NAME=C              LC_ADDRESS=C
#> [10] LC_TELEPHONE=C         LC_MEASUREMENT=C.UTF-8 LC_IDENTIFICATION=C
#>
#> time zone: UTC
#> tzcode source: system (glibc)
#>
#> attached base packages:
#> [1] stats4    stats     graphics  grDevices utils     datasets  methods
#> [8] base
#>
#> other attached packages:
#>  [1] SummarizedExperiment_1.42.0 GenomicRanges_1.64.0
#>  [3] Seqinfo_1.2.0               MatrixGenerics_1.24.0
#>  [5] matrixStats_1.5.0           org.Hs.eg.db_3.23.1
#>  [7] AnnotationDbi_1.74.0        IRanges_2.46.0
#>  [9] S4Vectors_0.50.3            Biobase_2.72.0
#> [11] BiocGenerics_0.58.1         generics_0.1.4
#> [13] limma_3.68.5                ctdR_0.99.11
#> [15] BiocStyle_2.40.0
#>
#> loaded via a namespace (and not attached):
#>   [1] DBI_1.3.0                   httr2_1.3.0
#>   [3] GSEABase_1.74.0             rlang_1.3.0
#>   [5] magrittr_2.0.5              otel_0.2.0
#>   [7] compiler_4.6.1              RSQLite_3.53.3
#>   [9] DelayedMatrixStats_1.34.0   png_0.1-9
#>  [11] systemfonts_1.3.2           vctrs_0.7.3
#>  [13] memuse_4.2-3                SpatialExperiment_1.22.0
#>  [15] pkgconfig_2.0.3             crayon_1.5.3
#>  [17] fastmap_1.2.0               magick_2.9.1
#>  [19] dbplyr_2.6.0                XVector_0.52.0
#>  [21] labeling_0.4.3              rmarkdown_2.32
#>  [23] tzdb_0.5.0                  graph_1.90.0
#>  [25] ragg_1.5.2                  purrr_1.2.2
#>  [27] bit_4.6.0                   xfun_0.61
#>  [29] cachem_1.1.0                beachmat_2.28.0
#>  [31] jsonlite_2.0.0              blob_1.3.0
#>  [33] rhdf5filters_1.24.1         DelayedArray_0.38.2
#>  [35] Rhdf5lib_2.0.0              BiocParallel_1.46.0
#>  [37] irlba_2.4.1                 parallel_4.6.1
#>  [39] R6_2.6.1                    bslib_0.12.0
#>  [41] RColorBrewer_1.1-3          jquerylib_0.1.4
#>  [43] Rcpp_1.1.2                  bookdown_0.48
#>  [45] knitr_1.52                  GSVA_2.6.6
#>  [47] readr_2.2.0                 Matrix_1.7-5
#>  [49] tidyselect_1.2.1            abind_1.4-8
#>  [51] yaml_2.3.12                 codetools_0.2-20
#>  [53] curl_8.0.0                  lattice_0.22-9
#>  [55] tibble_3.3.1                withr_3.0.3
#>  [57] KEGGREST_1.52.2             S7_0.2.2
#>  [59] evaluate_1.0.5              desc_1.4.3
#>  [61] BiocFileCache_3.2.0         Biostrings_2.80.2
#>  [63] pillar_1.11.1               BiocManager_1.30.27
#>  [65] filelock_1.0.3              vroom_1.7.1
#>  [67] hms_1.1.4                   ggplot2_4.0.3
#>  [69] sparseMatrixStats_1.24.0    scales_1.4.0
#>  [71] xtable_1.8-8                glue_1.8.1
#>  [73] tools_4.6.1                 BiocIO_1.22.0
#>  [75] data.table_1.18.6.1         ScaledMatrix_1.20.0
#>  [77] annotate_1.90.0             fgsea_1.38.0
#>  [79] XML_3.99-0.25               fs_2.1.0
#>  [81] rhdf5_2.56.1                fastmatch_1.1-8
#>  [83] cowplot_1.2.0               grid_4.6.1
#>  [85] SingleCellExperiment_1.34.0 HDF5Array_1.40.0
#>  [87] BiocSingular_1.28.0         cli_3.6.6
#>  [89] rsvd_1.0.5                  textshaping_1.0.5
#>  [91] S4Arrays_1.12.1             dplyr_1.2.1
#>  [93] gtable_0.3.6                sass_0.4.10
#>  [95] digest_0.6.39               SparseArray_1.12.3
#>  [97] rjson_0.2.23                farver_2.1.2
#>  [99] memoise_2.0.1               htmltools_0.5.9
#> [101] pkgdown_2.2.1               lifecycle_1.0.5
#> [103] h5mread_1.4.1               httr_1.4.9
#> [105] statmod_1.5.2               bit64_4.8.6